Comments

Wednesday, April 11, 2018

Bale and Reiss formalism

Bill Idsardi & Eric Raimy

[Note: in this post ordered pairs and tuples will be enclosed in parentheses, (x,y), instead of with angle brackets, <x,y>. The Blogger platform tends to eat the angle brackets, which it interprets as malformed HTML. Yes, we could do it with HTML character entities, but that's painful to edit.]

Warning: this post is also not light bedtime reading.

We think that it will be instructive now to examine the Bale & Reiss (forthcoming; BR) formalism for phonology. Although their book is “just” an introductory text it is their laudable intent and very impressive achievement to be rigorous and didactic in building up their formalism. They start out with basic set theory, and they make it all very accessible to beginners, building it up piece by piece. Consequently the book is extremely clear on many matters that (all) other intro texts are vague or silent about. And we feel that the book is very successful in this regard. But (you guessed it) we have some qualms about their treatment of precedence.

In their formalism, BR have:
  1. Values, drawn from W = {+, -}
  2. Features, drawn from F = {high, low, … } -- a finite set
  3. Feature-value pairs, elements of S = W x F -- also finite
  4. Segments, which are consistent sets of feature-value pairs (p 377); see below -- also finite
  5. Forms, which are tuples of segments (p 36, pp 101-103) -- this is intended to be an infinite set
Notice that there is no mention of time or precedence here yet, so we’ll have to wait to see how that’s constructed (hint: it’s in 5, sort of).

Here’s the definition of Consistency (BR 445):

So consistency is a well-formedness condition on segments, for it goes above and beyond the set requirement by itself, as {(+,high), (-,high)} is a set of feature-value pairs. Like our discussion of EFP features a few posts ago, this is a NAND condition, +high NAND -high, it’s just a little harder to state now without a basic notion of events since it has to be stated as a condition on certain sets of features (absent a clear notion of time) rather than as a conjunction of properties of an event. That is, since segments are constructed as sets of features, the condition is stated as a condition on sets. The way it’s formulated, it quantifies over sets (A set of features …) and also over features inside those sets (no feature …) and consequently this is a second-order statement since it is quantifying over sets. However, since the set S is finite, the work done by this definition could instead be done by exhaustively listing the licit combinations (the consistent elements of the power set pow(S)) without using any quantifiers.

Without an available formal notion of time at this point, it’s a little difficult to know what to make of the segment datatype. The latent idea, so far unexpressed in the formalism, is that the segments are sets of feature-value pairs, maybe occurring “at the same time, more or less” or "overlapping in time, more or less" or something like that. But that’s not formally expressed yet, except by allusion in the name of the construct, “segment”. Presumably some statements in the transducers handle the relationships between the elements of a segment and their motor and auditory correlates. Therefore, without knowing what's in the transducers, it's hard to know if "being together in a segment" is a substantive notion or not. If there is some property such as approximate temporal overlap that's veridical with "in the same segment" then the notion would seem to qualify as substantive (at least as we understand it, i.e. veridical and useful). But Chomsky 1964's arguments regarding linearity are very powerful here, and strongly suggest that there is no obvious veridical notion in the overall mapping from UR to phonetics. So in that case, segments could be a purely formal part of the theory, with their in-the-same-set-edness not mapping to any consistent property in the motor or perceptual systems. That is, the transductions for segmenthood would be "interesting"; we think this is Veno's view at least.

But this will also depend on what the rule system does in the phonology, and therefore we shouldn’t be too hasty to think that the linearity arguments directly establish this point for SFP. One of Chomsky's linearity arguments was the comparison between “writer” and “rider”. With rules of flapping and vowel lengthening, the LTM (UR) distinction between /rayt+r/ and /rayd+r/ is mapped to a surface difference in the length of the preceding vowel [rayDr] and [ra:yDr] (these are Chomsky's transcriptions). So the derivation as a whole, as well as the LTM representation do not respect a condition of linearity with "phonetic" representations. But what about the output forms of the phonology, [rayDr] and [ra:yDr]? How do they fare with respect to linearity with the motor and auditory forms at the interface? Better, certainly, but are they "phonetic enough" to find a veridical relationship with specified aspects of the motor and perceptual systems, especially at the point of interface? This seems like a hard, and important question.

Moreover, if features are substantive, the +high NAND -high condition has at least a potential lawful relationship to the co-domain motor and perceptual conditions, i.e. mot(+high) NAND mot(-high) and also aud(+high) NAND aud(-high), where mot() and aud() are the transductions with the motor and auditory systems respectively. If these NAND statements are true motor and perceptual statements, then the consistency requirement is recapitulating motor and perceptual conditions within the model (as we -- er and wji -- think it probably should). But this isn’t entirely substance-free then. What would be a (purely) formal (and non-substantive) universal is if we could show that it is NOT the case that mot(+high) NAND mot(-high) and also not the case that aud(+high) NAND aud(-high). Then having +high NAND -high in the phonology would be a phonological truth without any motor or perceptual connection or motivation. And depending on the actual content of mot() and aud() that could perhaps be the case, but we need some actual proposals for mot() and aud() in order to evaluate that. If so, then +high NAND -high could be an example of a pure phonological delusion, of the type that Charles suggested last week.

Now to the forms. For much of their presentation, BR just call them strings without saying what that means formally. But we do find out on p 36 that they intend them to be what they call “ordered sets”, which they then tell us are tuples, see also BR chapter 18. We wish they hadn’t used the term “ordered set” because that term already has an established meaning in mathematics as a structure (S, R) where S is a set and R is a relation of order over the set, e.g. Schröder 2003 Ordered Sets. The more usual treatment would be to define strings inductively using concatenation (e.g. Harrison 1978).

OK, so what’s a tuple? Using tuples for this purpose brings up some very interesting issues. Counting up by size, there is only one 0-tuple, (). (Bale and Reiss use angle brackets, <>.) The 1-tuples are from S, notated (x), the 2-tuples are from S x S, notated (x,y)  -- think points on a plane -- the 3-tuples from S x S x S (x,y,z) -- think points in 3D space -- and so on. A problem here is that unless there is a fixed upper limit on the size of the tuples, then this is not finitely axiomatizable in first-order logic as it requires an infinite number of statements. This issue has a famous history in the case of arithmetic, Ryll-Nardzewski 1952, Mostowski 1952, Montague 1964. (I [wji] already commented on the blog about problems like this in regard to < and successor. You need transitive closure of successor to get <, and that’s not first-order finitely axiomatizable.) There are alternative definitions for tuples using nested tuples, but that doesn’t get us out of the problem here, which is ultimately one of inductive (recursive) definitions. This seemingly innocuous move trips up many, many people (see Keller 2004, Some Remarks on the Definability of Transitive Closure in First-order Logic and Datalog).

Also unhelpfully, the types for tuples are all different from each other, as (x,y) has nothing to do with (x,y,z). (Hutton 2016:26 is helpful here as are the discussions in formal semantics of things like transitive (e, (e,t)) and intransitive (e,t) verbs.)

So how do BR get precedence? The way they do this is to invoke a convention to index the components of the tuples (BR pp 101-1033); their discussion refers to them primarily as strings.
"These strings have an implied left-to-right linear order and are equivalent in structure to ordered sets written with angled brackets, as we discussed above. For example, the mental representation of the word man will be mᴹæᴹnᴹ which is equivalent to <mᴹ, æᴹ, nᴹ>." (p 101)
"We use various numeral subscripts, or indexes, not only to distinguish between the variables but also to indicate their relative position in a string. Thus, if x₁x₂x₃ = mᴹæᴹnᴹ, then x₁ = mᴹ (the first member of the string), x₂ = æᴹ (the second member of the string), and x₃ = nᴹ (the third member of the string)." (p 102)
As could be predicted, we're not keen about implied representations for precedence or order and would much prefer an explicit notation for it instead. We're also not sure what "left-to-right" means other than something about typography. Is this a statement about how phonological representations map to temporal relations in the motor or auditory system?

But in addition, there are a couple of other issues with doing things this way. First, we don’t have any numbers yet because (1-5) didn’t provide any. So we have to give ourselves an infinite ordered set (in the usual sense, e.g. Schröder 2003), presumably the natural numbers N, which, as we said, are also not first-order finitely axiomatizable. When we have the numbers we can get the definitions that BR give, once we actually do the tuple indexing. It’s obvious how to do it, but since we are being formal, then we still need to say it. So here it is:
  • For all forms (x,y), x has index 1, y has index 2
  • For all forms (x,y,z), x has index 1, y has index 2, z has index 3
  • For all forms (w,x,y,z), w has index 1, x has index 2, y has index 3, z has index 4
  • ...
But now we’ve got the whole set of natural numbers in phonology. Do we really want them in there? Now we can talk about things like the 25th segment, do we want to be able to do that? There is another way out, without using any numbers or indexes. We can instead define the precedence relations directly on the components of the tuples, as follows:
  • For all forms (x,y), x^y
  • For all forms (x,y,z), x^y and y^z
  • For all forms (w,x,y,z), w^x and x^y and y^z
  • ...
You get the picture. (By the way, we’re quantifying over tuples of sets of feature-value pairs here.) Now we don’t need any numbers, and we can’t talk about segments by their position indexes because there aren’t any. And, as you could guess by now, this isn’t finitely axiomatizable either, because there would be an infinite set of these statements. This is why programming languages like Haskell have datatypes like lists, and strings are then lists of symbols. Then, at least, we can write an inductive definition on the size of the list (which we could mimic here using nested tuples, which are just cons cells by another name). That’s still not a first-order finite characterization, but it seems pretty clear that we’re not going to get one by proceeding this way, going up through sets and tuples, ending up with an infinite set of types.

In summary, precedence isn’t a primitive in the BR treatment, instead they build it out of feature-value pairs, sets, tuples and indices. Doing it this way is not first-order finitely axiomatizable. But it is finitely axiomatizable if we do it with events, properties and precedence as primitives.

So what’s the upshot here? Do these arcane points about finitary vs infinitary logic really matter? Are first-order and finiteness too much to ask? Probably. We would be content with monadic second-order (MSO) definable theories (which are first order plus quantification over monadic properties, like (*10) from the Boring details post, even though we rejected (*10)). Why are we ok with MSO? For one, this seems consistent with theories of semantics that we like (Pietroski) and MSO over strings is one characterization of the set of regular (= finite-state) languages, making a connection to the sub-regular hierarchy. But if we can bring everything down to first-order, then so much the better.


Monday, April 9, 2018

Arbitrary, or dogs and cats

Bill Idsardi

In recent comments Veno has put one part of the SFP view very succinctly and clearly:


"In other words, phonology (as an aspect of the mind/brain) treats features (and other units of phonological representation) as arbitrary symbols. From the point of view of phonology, then, features are substance-free units. This, of course, does not mean that features are not related to phonetic substance, and such a conceptualization of features does not preclude the construction of a neurobiologically plausible interface theory (even spelled out in Marr’s terms)."

So I think we need to unpack what "arbitrary symbols" means here. To put my cards on the table, when I read "arbitrary" I think of two things: the use of arbitrary in mathematics (meaning "anything meeting the definition") and Saussure's arbitrariness of the sign. My worry is that this view tends to exclude an important middle, the existence of abstraction -- distinct, but non-arbitrary relationships between levels of representation, call it hidden substance (because it's useful and partly veridical). And I think such non-arbitrary relationships of abstraction play an important role in sensory systems, and constitute the "substance" (or "substantive relationship") between adjacent levels of representation (being veridical and useful). So what we're going to uncover in this blog post are a few instances of "hidden substance". A word of warning -- this post might not make for light bedtime reading. On the other hand, it might be very soporific.

Let's start with a simple example of a non-arbitrary system, the unary numeral system, or tally marks. In this system for the natural numbers, 0 is the empty string, 1 = "|", 2 = "||", 3 = "|||" and so on. This is a non-arbitrary system because "more is more": larger numbers are represented with larger representations (larger numbers correspond to larger data structures). And addition in this system is concatenation, which then automatically (and non-arbitrarily) preserves important properties like being associative and commutative. So this isn't purely Saussurean as the representations have hidden substance (or partial substance if you prefer). Onomatopoeia (sound-symbolism) is another kind of in-between case, and it might be helpful at least as an analog in understanding the point here, namely that there's still some substance (veridicality and usefulness) but it has been partly obscured by the mapping (but this analogy is imperfect, and I really don't want to discuss theories of sound-symbolism here). It is also obscured by the fact that many other mappings are much more arbitrary (e.g. Roman numerals). Perhaps another way to think about this idea would be to say that arbitariness can be put on a scale of how much of the system is done via lookup tables, and how much of the system is done by general laws of combination (see Gallistel and King 1999).

Sensory systems, even mechano- and chemo-transducers, tend to do a similar kind of abstraction in lawfully transmitting some relationships. But admittedly those cases are not nearly as clean as the unary numerals toy example. For example, the conversion done by the rod cells in the retina also abides by "more is more" -- within the operational limits more photons received means more activity. (At the low end the limit reaches down to a single photon, at the high end, the rods reach saturation pretty quickly, leaving the rods relatively less to do for humans in the modern built world.)

I think the intended use of arbitrary in Veno's quote is for something like "substitutable, interchangeable in the functions, operations and/or relations". This is also what I take to be the point of the dogs-cats argument, which is in Bridget's article that she mentioned in response to our first post. Here's Bridget quoting Daniel Currie Hall, channeling Alec Marantz.


"The phonological component does not need to know whether the features it is manipulating refer to gestures or to sounds, just as the syntactic component does not need to know whether the words it is manipulating refer to dogs or to cats; it only needs to know that the features define segments and classes of segments. The phonetic component does not need to be told whether the features refer to gestures or to sounds, because it is itself the mechanism by which the features are converted into both gestures and sounds. So it does not matter whether a feature at the interface is called [peripheral], [grave], or [low F2], because the phonological component cannot differentiate among these alternatives, and the phonetic component will realize any one of them as all three." (p 206)

I have a couple of comments about this argument. First, I think that  the appropriate comparison for phonology is semantics, not syntax, because it is semantics that connects to the CI interface. That is, the question is whether the difference between dog() and cat() is semantically substantive, not if they are syntactically distinct. But the argument is presented in various places ranging across both semantics and syntax. And to be clear, I think this observation about cats and dogs is correct about both syntax and semantics. That is, interchanging cat() for dog() doesn't affect the nature of the syntactic or semantic computations, though it might eventually end up in different truth values for particular instances (e.g. dog(laika) vs cat(laika)). (And this is not an endorsement on my part of truth-value-oriented semantics, see Pietroski, but it will do for this discussion.)

The issue I have with the argument is simply that the range of semantic examples (cats vs dogs) is too narrow to reveal the hidden semantic substance. These cases both have the same type, (e,t). The important question is not about dogs and cats but about dogs and some item with a different type, like all which has type ((e,t), ((e,t),t)). Is the difference between dogs and all important within the semantic computation? The answer would seem to be yes -- that's the whole point of having a type system. And consequently, the difference between dogs and all is again a kind of hidden substance, only now between the CI notions DOG and ALL that map to dogs and all. That is, the difference between DOG and ALL in the CI system maps to a type difference in the semantics between (e,t) and ((e,t), ((e,t),t)). Consequently we should restrict the notion of free substitution to substitution between items of the same type. For me, this interchangeability notion is not a question of being "substance-free" (although one might say that the calculations are substance-agnostic, adapting Thomas Graf's use of "content-agnostic" from his reply to Norbert's post), rather the idea seems more closely related to the notion of systematicity (Fodor and Pylyshyn 1988, Aizawa 2003).

So let's try to translate the free-substitution-within-types idea into the proposed EFP structure to try to find cases of hidden substance. The resulting claim, which we largely agree with, would say that all events are freely interchangeable with other events without affecting the nature of the computation, all features are interchangeable with other features, and all precedence relations are interchangeable with other precedence relations. Not, importantly, that there are no differences between events and features and precedence relations, which all have different type signatures (in a "truth-value" phonology they would be (e), (e,t) and (e,(e,t)) respectively). So, we'll say a little boldly, type differences indicate hidden substantive differences. But having hidden substance isn't being "substance free" though it does make it harder to spot.

Free substitutability is certainly a situation "devoutly to be wished", even when restricted to items of the same type, but I'm afraid we will still fall a little short of this ideal. Why? Because there are the dreadful "special cases", meaning more examples of hidden substance. In the EFP model, the # and % events are special cases, which means that they aren't fully interchangeable with other (ordinary) events. An automatic consequence of their special status is that the precedence relations involving # and % are not fully interchangeable with other precedence relations either. And furthermore that there are no features that apply to # and % events. (I.e. [spread]e for e = # isn't a thing, though see this exchange between Lass and Morris Halle.) One way of thinking about this is that # and % are "purely formal", but that again highlights that the difference is one of substance -- either the special events don't have any (which seems not quite right), or they have weird, special properties that are preserved across the interface ("beginning/end of form").

This is similar in some respects to math cases where certain Abelian groups are extended to form fields. In those cases we need to "special case" the identity element over addition (0) to say that it does not have a multiplicative inverse (i.e. 0 has no reciprocal, or you can't divide by 0). I think in general we are so used to these special cases that we often fail to even notice them. So let me point out a very general source of special cases. In a recursive definition, the special cases will be the base cases (= stopping cases), like "end of string" or 0. Are there any additional special cases for events, features or precedence beyond the ones just noted? Unfortunately, we suspect that there are some more. Again, the minimalist program qua program is to try to keep the special cases to a minimum, not to declare them all out-of-bounds a priori.

To bring this post to another bumper-sticker conclusion, the hidden substance cases show that arbitrary ≠ systematic ≠ substance-free. We need to keep these notions separate, because they interact in interesting ways in complex, modular systems like language.

Methodological sadism

Methodological sadism (MS) is quite fashionable nowadays and nothing gets practitioners more excited than the possibility that someone somewhere is proposing something interesting (i.e. something that reaches beyond the sensory surface of things and that might possibly reveal some of the underlying mechanics of reality). You’ve all met people like this,[1] and one of their distinctive character traits is a certain (smug?) assurance that when it comes to the philosophy of science, they are on the side of the angels. They love to methodologically demarcate the boundaries of legitimate inquiry so as to protect the weak minded from fake science.

Of course, the standard demeanor of MSers is severe. Yes they are tough. But standards must be maintained lest we slide joyfully to our scientific perdition. Like I said, you’ve all met MSers. Nowadays, at least in my little domain of inquiry, they are the media stars and have done a pretty good job convincing the outside world (and some on the inside) that GG is dead and that there is really nothing special about the cognitive powers required for language. I think that this is deeply wrong, and will write another brief arguing as much in the next post. But for now, I want to, once again, offer some prophylaxis against the most rabid form of MS, falsification.  Here is a useful short antidote, a paper (which I will refer to as ‘AB’ (Adam Becker is author)) that touches all the right themes. Its main claim is that trying to demarcate science from non-science is a mugs game that relies on ignoring how real successful domains of inquiry have grown.

So what are the main themes?

First AB points out that SMers (my term not AB’s) adhere to a basic erroneous principle: “that a new theory shouldn’t invoke the undetectable” (2).[2] Why? Because this makes it “unfalsifiable.”  So, observability underlies falsifiability and both are used by “self-appointed guardian[s], who relish dismissing some of the more fanciful notions in physics, cosmology and quantum mechanics [and linguistics! NH] as just so many castles in the sky” in order to protect science from “from all manner of manifestly unscientific nonsense” (2).

There are ways of understanding falsifiability that seem unobjectionable, namely that theories that never can have observable consequences are thereby undesirable. Well, yeah. The problem is that this is a very low bar, and any stronger version that “turn[s] ingenuity into fact” must be “much more nuanced” (2). Why? Because falsifiability is hardly ever possible and observability is undefinable. Let’s consider both of these facts seriatim.

First falsifiability. This is impossible for scientific theories for the simple reason that any falsification can be patched up with the right ad hoc statement, leaving the rest of the theory the same. As AB puts it (correctly) (2):

Falsifiability doesn’t work as a blanket restriction in science for the simple reason that there are no genuinely falsifiable scientific theories. I can come up with a theory that makes a prediction that looks falsifiable, but when the data tell me it’s wrong, I can conjure some fresh ideas to plug the hole and save the theory.

Any linguist knows how true this is. Moreover, it is easier the less brittle a theory is, and our current theories tend to be very labile. You can bend them in many directions without ever hearing a creak let alone inducing a crack or a break. You loose nothing when adding a bespoke principle to explain recalcitrant data because the only thing there is to loose in doing this is explanatory power and there was not much of this to begin with in flexible theories. However, even with good theories that have some oomph, it is generally possible (I would say “always possible” but I am being mealy mouthed here) to plug the hole and carry on.  One of the virtues of AB is that it provides some nice historical examples of this happening. As AB notes, the history of science is full of them.

AB recounts the famous one where Uranus’ odd (apparently non Newtonian) orbit begats Neptune, which in turn begats Vulcan to explain Mercury’s perihelion which finally fails when General Relativity replaces Newton. AB notes that each historical move makes sense and that looking for Neptune (victory!) and looking for Vulcan (failure!) were both rational despite the different outcomes.  Of course, with hindsight, Neptune is a bold prediction that strengthens the theory and Vulcan turns out to have been just an unfortunate wrong turn. But Vulcan did not lead to people jumping the Newtonian ship. Rather “astronomers of the time collectively shrugged and moved on” (4). And rightly so. Do you really want to give up Newton just because Vulcan was impossible to spot? What then do you do with all the other stuff it does explain?

Note that this means that there is an asymmetry between potentially falsifying experiments that succeed and those that don’t. The former are declared as triumphs of the scientific will, while the latter are quietly shelved and de-emphasized (or, more accurately, added to the ledger of anomalies that a discipline collects as targets for yet unknown superior explanations yet to come). No reason to show these off in public and take the shine from the powerful rational methods of scientific inquiry.

Of course, one might eventually hit the jackpot and find the anomalies resolved with the right new theory. Mercury was a feather in General Relativity’s cap. And well it should have been, for it allowed us to dump Vulcan and replace it with a story that allowed us to also keep all the good parts of Newton. So yes exceptions prove the rule in the sense that Newtonian exceptions prove (justify) Relativity’s rules.

AB provides other examples, one of the best being Pauli’s proposal to save the Law of the Conservation of Energy via the neutrino. It took over 25 years to prove him right (it’s good to have descendants like Fermi who get interested in your ideas). But what is interesting is not merely the long wait time, but why it took so long: the neutrino had no properties at the time that Pauli proposed it that could have allowed it to be detected. So when Pauli proposed it, the theory was unfalsifiable because its basics were unobservable. But, as history shows, wait 25 years and who knows what unobservables might become detectable. As AB again, rightly, puts it (5):

It’s certainly true that observation plays a crucial role in science. But this doesn’t mean that scientific theories have to deal exclusively in observable things. For one, the line between the observable and unobservable is blurry – what was once ‘unobservable’ can become ‘observable’, as the neutrino shows. Sometimes, a theory that postulates the imperceptible has proven to be the right theory, and is accepted as correct long before anyone devises a way to see those things.

Not only is ‘observable’ irreparably vague, but MSers also often make a second more extreme demand concerning its applicability. They require theory to only postulate constructs with directly observable magnitudes. Laws of nature then simply relate “directly observable quantities” and make no reference “to anything unobservable at all” (6). This was essentially Mach’s views and, in hindsight, they served to hamstring scientific insight. For example, as AB notes, Mach opposed atomic theory as unscientific. Why? Well you cannot “see” atoms. Of course, as many pointed out, there is lots to be gained by postulating them (e.g. you can derive the principles of thermodynamics and explain Brownian motion). But this was not good enough for Mach, nor for current day MSers. So how did Mach’s views hold up? Well, it cost Walter Kaufman a Nobel Prize apparently and might have led to Boltzmann’s suicide, but aside from that it did not do any real damage because the scientific community largely ignored Mach’s injunctions.

But isn’t postulating unseen elements unscientific? Well no. Note: even if we all agree that theory must have discernible (aka observable) consequences so that it can be tested/verified, this does not imply that every part of the theory must invoke elements whose properties are directly observable. Of course, it is nice if one can do this. It is always nice to be able to measure. But the idea that the only thing worth doing is relating (perhaps statistically) the magnitudes of observable quantities is something that would sink our best sciences if implemented. And this is a good reason not to do it![3]

One can go further, and AB does. The notion of an observable is itself fundamentally obscure. It cannot mean, observable given “current” technology, for that is too strong. As the history of the neutrino “discovery” indicates, taking this position would have led away from the truth, not towards it. But it cannot mean “observable in principle” for this is irremediably vague. If we mean that it is not “logically possible” to observe what but contradictions will fail. If we mean given current technology or current theory it is too strong. So what then? AB, quotes Grover Maxwell as observing” “There is no a priori or philosophical criteria for separating the observable form the unobservable.” The best we can say is that theories with observable consequences are better situated than those without ceteris paribus. But what goes into the ceteris paribus determination is forever up for grabs, and subject to the inconclusive (yet critically important) vagaries of judgment. No method, just mucking around, always.

AB makes a last observation I’d like to highlight: unlike many, AB emphasizes that part of the scientific enterprise is building “sky-castles.” This is not a scientific aberration, nor an example of science misfiring, but part of the central enterprise. For the scientist (including the linguist see here) “[s]pinning new ideas about how the world could be – or in some cases, how the world definitely isn’t – is central to their work” (2). Explanation leans heavily on the modal ‘could’ in the quote. Not just what you see or mild extensions thereof, but what could be and couldn’t. That’s the stuff of understanding and as AB notes, again rightly, “[the] goal of scientific theory is to understand [my emphasis, NH] the nature of the world with increasing accuracy over time.”

Methodological sadists, if given power, would sink scientific inquiry. They would make it nearly impossible to uncover unobservable mechanisms for they are an inherent part of all decent explanation in the sciences. MSers undervalue explanation and hence distrust the speculation required to get any. As AB notes, their dicta are at odds with the history of science. They are also deeply obscure. So historically misguided and irredeemably obscure? Yes, but also sadistically useful. MSers sound tough minded (just the facts kinda people) but really they are hopeless romantics, stuck with a view of method and inquiry that successful inquiry has largely ignored, as linguists should as well, at least if they want to get anywhere.


[1] Pullum, Haspelmath, Tomasello and Everett are prominent examples of such in my own little world.
[2] The strong form would say that no theory should, not only new ones. However, MSers generally aspire to be gatekeepers and, in practice, this means keeping out the new. Facing out, rather than in, also has one important advantage. It is pretty hard to argue that accepted results are suspect without making one’s methodological injunctions sound dumb (recall, that every modus ponens comes with an equally powerful modus tolens). Consequently, fire is reserved for the novel, which is always deemed to differ from the accepted in being methodologically deficient. Note that being methodologically deficient has its virtues in argument. It relieves the critic of actually having to go into details, of having to do the hard work of arguing against actual results. MSers generally paint with a broad methodological brush, and I would argue that this is the reason why.
[3] Linguists here should be thinking of those that take Greenberg universals to be the only kinds that are legit (e.g. the crowd in note 1). Why do this? Well because as MSers they demand that science eschew the unobservable. Greenberg universals just are estimates of co-occurrence (either categorical or probabilistic) among surface visible language properties. Chomsky universals are not, and this is why for MSers Chomsky Universals are verboten.

Saturday, April 7, 2018

Boring details

Bill Idsardi & Eric Raimy


Recall from last time that we are trying to formalize phonology in terms of events (e, f, g, … .; points in abstract time), distinctive features (F, G, … ; properties of events), and precedence, a non-commutative relation of order over events (e^f, etc.). So far, together this forms a directed multigraph.

Inspired by a challenge from Greg Hickok, we’ll see how far we can get with those things without assuming explicit constructs such as sets of features constituting segments (viz subgraphs, more on this in a later post). We will try to avoid falling victim to the pitfalls cautioned against by Kazanina, Bowers & Idsardi 2017 by allowing events to have multiple properties (but we won’t bother collecting up such properties into sets either). Another way to put this point might be to say that we will attempt to cast segments as an emergent phenomena, arising out of features and order (oooh, that sounds so much better). We picked events, features and precedence for inclusion in the model precisely because they are substantive (admittedly, the points in time are pretty abstract), and provide a reasonable starting point for effectual interfaces to action and perception.

Special shit we need:

  • #: an event such that ∀ e NOT e^# (yes, this entails NOT #^#)
  • %: an element such that ∀ e NOT %^e (yes, NOT %^%)
  • $: an empty element, see below. (Think juncture or instantaneous $ilence.)

# codes the beginning of time. (Not the Big Bang, just the abstract time under consideration in the current “workspace”.) % codes the end of time. (And I can’t bring myself to search for a Big Bang Theory quote.) # and % are always available. (I.e. in every workspace instance, see below. We’re building toward MERGE for workspaces. Ideally MERGE(π1,π2) is just the simple union of events, features and relations in both workspaces. But there’s no way it’s quite that simple.)

Another piece of substance that we might want to include is logical relationships among properties. We believe that some of these are universal, but some could also be induced by the learner and so could vary across languages. In particular, for now, we will include the basic feature co-occurrence restrictions and dimensional organization from Avery & Idsardi 1999 (A&I). (In a later post we’ll back off on this and see what being more permissive can buy us.) In the present context this means a couple of things. First, we include in the model the substance of the agonist/antagonist organization of the features (where a NAND b = NOT (a AND b), showing that I [wji] have been disparaging NAND for too long [fn: NAND and NOR are the only logical primitives that alone form a complete basis for the binary logical functions]):

(1) NANDs

  • [spread] NAND [constricted]
  • [stiff] NAND [slack]
  • [raised] NAND [lowered]
  • [high] NAND [low]
  • …

Again, we see this as an empirical claim about phonology. If a good use for e.g. [high, low] events can be found then these conditions should be dropped. (And this is the sort of thing that we will explore later.) These are well-formedness conditions on phonological representations, and would govern rules//laws such that all rules/laws have to obey (1); (1) counts as part of the theory of “possible phonological rule/law”. How they manage to obey (1) is a matter for investigation. 

Second, there are statements like IF F THEN G, meaning  ∀ e IF Fe THEN Ge. (We don’t use the usual symbolic logic symbol for implication, →, because we also want to do graph operations as rules which will also use →.  Another common symbol for implication, ⊃, is also used in set theory, so it has similar problems. So we’ll just spell it out.) Therefore, UG has statements like the following:

(2) IF-THENs

  • IF [spread] THEN [GW]
  • IF [GW] THEN [Laryngeal]
  • ...


If we want to go the whole way to capturing the “bare dimensions” in the A&I framework (and at least one of us does), then we would also have statements like:

(3) XORs

  • IF [GW] THEN [spread] XOR [constricted] 


Given (1), could use OR here instead as F XOR G = (F OR G) AND (F NAND G). (3) would hold at the interface to the motor system but only there, i.e. no bare [GW] sent to the motor system, but bare [GW] is a possible representation in LTM (see A&I) or from the auditory system (= “there was something funky with the voice quality, but I’m not sure what”). This allows for special kinds of underspecification. Anthropomorphizing, a simple [GW] event on its way to the motor interface doesn’t yet know if its [spread] or [constricted] but it will be one or the other (called completion in A&I). 

So far, we believe that this approach is broadly consistent with Jardine 2016. In our terms, Jardine adds another temporal relation (association) between events, we could notate that as e|f, indicating that e is associated to f. (On the “meaning” of association lines see Coleman and Local 1991, Sagey 1986, in the present context we could understand it as weak synchronization, “at about the same time”, recall Saberi & Perrott 1999). In that case there might also be universal restrictions on the combination of these two relations, something like ∀e,f IF e|f THEN NOT e^f AND NOT f^e. But given things like loops in time, this question is not nearly as simple as it first appears. Taking a minimalist position on this question, we will not include | here (but think about ASL again). 

To get theories like Mielke 2008, just start with a different set of features, ones that denote whole “segments,” e.g. [ʊ]e, and then invent/discover/define/select classificatory properties like [round]:

(*4) IF [u] OR [ʊ] OR [o] OR … THEN [round]

Since we’re not going to adopt Mielke’s approach either, we’ve put * in front of 4 to mean that we’re not including it in our model (using the * is actually us trying to trick syntacticians into reading along). Obviously, you could turn such statements around also, IF [round, high, back, ATR, …] THEN [u], but it’s not clear to us what work we would do with [u] if we’ve got the features already. For circuit fanatics, (4) implies a disjunctive relationship between “primary” and “secondary” percepts; if features come “first” then it’s a conjunctive coding in the “second layer” instead. (We're sure the brain does both kinds of things.) 

This brings us to an important point, we have not said anything about how many fneurons (features, properties) an event can have. We could include into the theory statements that make events as simple as possible, meaning that phonological representations would be maximally “scattered”, i.e. have a maximal number of events because each event would have at most one feature. The statement that would do this is:

(*5) ∀ F, G such that F ≠ G, F NAND G 

Statement (5) has an important property, it’s a monadic second order formula because it is  quantifying over properties. This is obscured because we wrote it in a "pointfree" style (the term is from Haskell), so let’s restate it making the event variable clear:

(*6) ∀ e ∀ F, G such that F ≠ G, Fe NAND Ge
(alternatively, ∀ e ∀ F, G IF [F, G]e THEN F = G)

We are quantifying over two different kinds of things, events and monadic properties, and the distinctness criterion (F ≠ G) is over properties, not events (which could be construed extensionally as the set of events Fe and the set of events Ge, but we will resist this interpretation and see properties and functions as first-class, as in Haskell). 

We think that Theory(*6) is an interesting idea to pursue, but we won’t include (*6) here either (we’re fickle like that). That means that events can have multiple properties for us.

Properties in either the articulatory and auditory system can certainly overlap in time. If such “bindings” are recognized by, say, the perceptual system, that information could be conveyed into the phonology as a single event with multiple properties, e.g. [front, round]e. In passing we note that what the phonology receives from perception can be incomplete or distorted in all sorts of ways, but that the phonology trudges on to LTM anyway, despite occlusion (phoneme restoration effects), tinnitus, temporally reversed speech, and so on. 

Consequently, we believe that one aspect of the phonological computation is to construct and deconstruct complex events, that is, to be able to split [front, round]e into [front]e, [round]f, fission, and vice versa (fusion), i.e. between (7) and (8) in either direction:

(7) 


(8) 


To do this we will almost certainly need a derivative relation on events, which is similar to the | we ascribe to Jardine. In a configuration like (8) we would say that e || f (“e is parallel to f”). (This will have to be generalized somewhat, something like a^e AND a^f AND NOT e^f AND NOT f^e.) If we do this generally in a language, then we could possibly capture the effects of line fusion in Government Phonology (Kaye, Lowenstamm and Vergnaud 1985). Another example of something like this might be Korean, in which all fricatives are strident, so we could fuse all parallel strident and fricative events. The net effect of this could be to impair the ability to detect (or possibly even to stably represent) non-strident fricatives. While we’re at this, if a rule can look for an environment like (8) then it’s probably also the case that a learning algorithm could examine such configurations to look for pairs of features that often occur in parallel, to find correlations or to learn event fusion/fission processes.

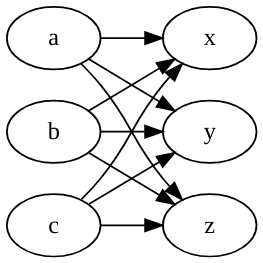
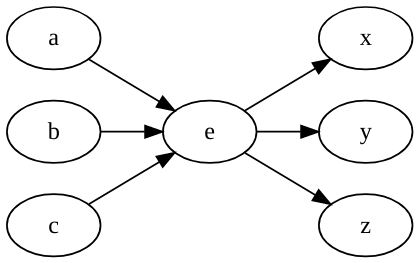
We return now to $, which we will define as an event without any properties, abstract silence or abstract juncture, a virtual pause. This is mostly for notational convenience, but it could turn out to be used as a basis for some segmentations. For example, sometimes the precedence statements that flow in from the perceptual system will form a bipartite graph between (groups of) events. That is, there will be events a,b,c and x,y,z such one cluster of elements mutually precede the other cluster:


The left-hand graph is the graph K3,3, and is one of the two identifiers for non-planar graphs (the other being K5). That is, no graph containing K3,3 can be represented in two dimensions without crossing lines. Perhaps in such cases a $ event e is inserted to establish planarity. (Though why abstract planarity would be important here is not at all clear.) Depending on how common this situation is, this could “chunk” events, or provide alignment possibilities to guide LTM access. 

We could add a clock, and thereby make a timing tier, but we won’t do that either for now. (But we think that such things will ultimately play an important role, see Gallistel & King 2009, and Giraud & Poeppel 2012. The auditory system does have a couple of endogenous clocks, see below.)

If you want to bring SPE back (we are repressing our inner Justin Timberlake here…) then you will need to:

  • add [+F] synonyms for every [F]
  • add all the [-F] definitions
    (IF NOT [+F] THEN [-F] since SPE didn’t allow underspecification), 
  • constrain temporal relations to be linear
    (∀ a, b, e IF a^e AND b^e THEN a=b; IF e^a AND e^b THEN a=b) 
  • constrain temporal relations to be complete
    (∀ e ∃ a, b such that e = # OR e = % OR a^e^b) 

Definitions for things like [αF] are left as an exercise for the reader. Although we like SPE, we won’t do this either.

Also we will include substance to the extent that it will allow for the identification of the articulator-free (manner) features. We’ll assume here that they are privatively coded [stop], [trill], [fricative], [liquid], [approximant], and that these interface to degrees and kinds of innervation to the articulators (i.e. a full ballistic gesture with [stop]). These, along with [nasal] are the landmarks of Stevens 2000 (see also various work by Carol Espy-Wilson and her colleagues), and constitute a proposal for a coarse-coded phonological “primal sketch” (Poeppel & Idsardi 2012). Given that we can have events with multiple properties, we can have events like [stop, Coronal] which would ultimately execute a full closure by the tongue blade. We can also if we want combine the insights of Clements and Rubach on affricates as strident stops with Steriade’s aperture theory. In such cases an event [stop, fric, Coronal, lateral] could be split into two events  [stop, Coronal]^[fric, Coronal, lateral] to interface with motor control. (For those wanting mutually exclusive coding of manner features, i.e. *[stop, fric] = [stop] NAND [fric], just drop the [fric] feature from the “abstract” starting representation for the affricates.) 

Finally, in order to interface with the dual timescale analysis being performed by the auditory system (Poeppel 2003, Giraud & Poeppel 2012), we will allow events which indicate syllables, σe. These events as they come out of the auditory system are innervated along a relatively slower time scale, in theta band (~ 4-8 Hz). The featural elements, like [spread], will be modulated by low gamma band oscillations (~ 20-40 Hz). Together (along with delta band) these form an endogenous clock (see Gallistel and King 2009) which permits the identification of precedence relations inside perception. It is also almost certainly the case that auditory streaming (Bregman 1990) affects the ability to identify precedence relations. Telling that a single neuron displayed an on-off-on pattern (and therefore concluding that ∃ x, y Fx^Fy) is easier than recognizing Fx^Gy for elements across streams, Fink, Ulbrich, Churan & Wittmann 2006. Is this enough by itself to induce “reflective” tier effects in the phonology? Would something like this make tier effects exogenous to the model (the perceptual input to the phonology is just more likely to include x^y statements within a stream)? We don’t think that there are easy answers to these questions.

Given how little specification that we have given to the model, there are few limits on what we can compute with it at the moment. But we are sure that this gives us enough “wiggle room” to capture the observations about linearity, invariance, and biuniqueness in Chomsky 1964.

We want to emphasize here that we do agree with SFP that the computation procedures within phonology are a complex, composed function, which is decomposable into simple functions, though here they are graph-theoretic operations (which are called transductions in that literature) on the events (nodes), properties (features) and precedence relations (links) in the phonological graph. Again, this is like Raimy 2000 without a timing tier, and Autosegmental Phonology without pre-defined tiers or association lines; just let precedence statements be stated between any pair of events, which might have any number of properties.

Next time: Dogs and cats

Wednesday, April 4, 2018

A modest proposal

Bill Idsardi and Eric Raimy


[Note: the following owes tremendous debts to Jeff Heinz and Paul Pietroski, but that does NOT imply their endorsement. But they can provide endorsements or disavowals in the comments if they want to. They also have the right to remain silent, because ‘Murica.]

Taking phonology to be the mind/brain model for speech, it needs to have interfaces to at least three other systems: the articulatory motor control system (action), the auditory system (perception) and the long term memory system (memory), forming a Memory-Action-Perception (MAP) loop (Poeppel & Idsardi 2012). Likewise, signed languages will have to have interfaces to action (the motor system for the hands, arms, etc.), perception (the visual system) and to memory. As discussed in the comments last week, we think therefore that sign language phonology probably also includes spatial primitives which spoken language phonology lacks. 

So the data structures inside phonology proper must be able to effectively receive and send information across those interfaces. This condition is a basic tenet of the minimalist program. Pietroski (2003: 198 Chomsky and his critics) is on-point and unmistakable :

"Indeed, a sentence is said to be a pair of instructions -- called "PF" and LF" -- for the A/P and C/I systems. If these instructions are to be usable by the extralinguistic systems, PFs and LFs may have to respect constraints that would be arbitrary from a purely linguistic perspective."

(And see Chomsky's replies in the same book for further remarks on the importance of the interface conditions, e.g. p 275.) That is, the data structures inside phonology must be sufficiently similar to the data structures in the directly connecting modules to allow for the relevant information to be transferred. Such interface conditions are also definitely part of Marr's program, though people seem to miss this point, perhaps because it's buried in his detailed account of the visual system, e.g. pp 317 ff on transforms between coordinate systems.

Reiss and Hale often refer to the interfaces as “transducers”, but the whole of phonology is a transducer between LTM and motor control, and between perception and LTM (“From memory to speech and back”, Halle 2003). (There also seem to be some connections between action and perception that do not include a way station at memory. We ignore those things here.) Moreover, at times the SFP proposals seem to imply transducers which would have very impressive computational abilities, and which look implausible to us as direct interfaces which can be instantiated in human neural hardware (which in perceptual systems seem largely limited to affine transformations and certain changes in topology and discretization such as are accomplished in the vision system, Palmer 1999, though see Koch 1999 for an idea of how much computation a single neuron might be able to do -- a lot).

So, first, we will adopt the proposals of Jakobson, Fant and Halle 1952 (minus the acoustic definitions, which are nevertheless very relevant for engineering applications), and Halle 1983 regarding distinctive features and their neural instantiation, but drawing the feature set from Avery & Idsardi 1999. Here is a relevant diagram from Halle 1983:


And here is A&I’s wildly speculative proposal:


We believe that SFP (or at least the Reiss & Hale contingent) is sort of ok with this, although they remain more open on the feature set (which for them continues to include things like [±voiced] -- by the way, also in the Halle 1983 figure above -- despite Halle & Stevens 1971, Iverson & Salmons 1995 et seq).

We understand the perception side to involve neural assemblies including spectro-temporal receptive fields (STRFs, Mesgarani, David, Fritz & Shamma 2008, Mesgarani, Cheung, Johnson & Chang 2014) and a coupled dual-time-window temporal analysis (Poeppel 2003, Giraud & Poeppel 2012). On the action side, we’ll go with Bouchard, Mesgarani, Johnson & Chang 2013 and another off-the-shelf component, Guenther 2014. Much less is known about the relevant memory systems, but we’ll take stuff like Hasselmo 2012 and Murray, Wise & Graham 2017 as some starting points.

Most importantly in our opinion (we've been telegraphing this point in previous posts) we need a reasonable understanding of what “precedes” is, and we think precedes needs to be front and center in the theory. We feel that it is very unfortunate that phonological practice has often favored implicit depictions of “precedes” (as horizontal position in a diagram) rather than being explicit about it (but we’ve rehearsed these arguments before, to not much effect). We take “precedes” to be a temporal relation at the action and perception interfaces, providing the basis in the phonology for notions such as “before” and “after” and “at the same time, more or less”. (And for speech “more of less” appears to be about 50ms, Saberi & Perrott 1999, again see Poeppel & Giraud & Ghitza &co. It's not impossible for the auditory system to detect changes that are faster than this, but such rapid transitions will be encoded in phonology as features rather than as separate events.) We feel that it bears repeating here that the precedes relation in phonology is interfacing to the data structures and relations for time that are available in motor control and auditory perception and memory, which themselves are not going to capture perfectly the physical nature of time (whatever that is). That is, the acuity of precedes will be limited by things such as the fact that there is an auditory threshold for the detection of order between two physical events. (A point that Charles brought up in the comments last week.)

There are a number of ways to construct pertinent data structures and relations, but we will choose to do this in terms of events, abstract points in time (compare Carson-Berndsen’s 1998 Time-Map Phonology in which events cover spans or intervals of linear time). This will probably seem weird at first, but we believe that it leads to a better overall model. NB: This is absolutely NOT the ONLY way to go about formalizing phonology. SFP (Bale & Reiss 2018) take quite a different approach based on set theory. We will discuss the differences in a later post or two.

Within the phonology that means that we have at least:

  1. events/elements/entities, which are points in abstract time. We will use lower case letters (e, f, g, ...) to indicate these.
  2. features, which we construct as properties of events. When we don’t care what their content is we will use upper case letters to indicate them (F, G, H, …). So Fe means that event e has feature F. We will enclose specific features in brackets, following common usage in phonology, e.g. [spread]e. Notationally, [F, G]e will mean Fe AND Ge. We will drop the event variable when it’s clear in context (think Haskell point-free notation).
  3. precedes, a 2-place relation of order over events, notated e^f (e precedes f). The exact “meaning” of this relation is a little tricky given that we are not going to put many restrictions on it. For example, following Raimy 2000, we will allow “loops in time”. We're not sure that model internal relations really have any "meaning" apart from how they function inside the system and across the interfaces, but if it helps, e^f is something like "after e you can send f next" at the motor interface and "perceived e and then perceived f next" at the perceptual interface.

(We’ll do things in this way partly because of Bromberger 1988, though I [wji] still don’t think I fully understand Sylvain’s point. Also, having (1-3) allows us to steal some of Paul Pietroski’s ideas.)


So far (1-3) give us a directed multigraph (it allows self-edges and multiple edges between nodes); and with it comes with no guarantees of connectedness yet. (And Jon Rawski would like us to point out that there's a fore-shadowing of a model-theoretic approach here. Jon, please say more in the comments if you'd like.) We suppose this thing needs a name, so let’s call it Event-Feature-Precedence (EFP) Theory (would PFE be better? that could be pronounced [p͡fɛ], as in “[p͡fɛ], that’s not much of a theory”). With (1-3) we have a feature-based version of Raimy 2000 (as opposed to its original x-tier orientation), but since we will allow events to have multiple properties (features), we can recreate Raimy diagrams, such as this one for “kitty-kitty” where the symbols are the usual shorthands for combinations of features.


And now, for some random quotes about non-linear time (add more in the comments, please!):

“This time travel crap, just fries your brain like a egg.” Looper

“There is no time. Many become one.” Arrival

“Thirty-one years ago, Dick Feynman told me about his "sum over histories" version of quantum mechanics. "The electron does anything it likes," he said. "It just goes in any direction at any speed, forward or backward in time, however it likes, and then you add up the amplitudes and it gives you the wave-function." I said to him, "You're crazy." But he wasn't." Freeman Dyson
(Note: Freeman Dyson is a physicist, not a movie).
We also take properties (features) to be brain states, as in Halle 1983. Then [spread]e means that event e has the property spread glottis. (For us being brain states doesn't preclude the properties from being other things too. We mean (1-3) in a Marrian way across implementations, algorithms and problem specifications.) This discussion will sometimes be cast as if features are single neurons. This is certainly a vast over-simplification, but it will do for present purposes. For us this means that a feature (= neuron (group)) can be “activated”. (The word “feature” seems to induce a lot of confusion, so we might call these constructs fneurons, which we will insist should be pronounced [fnɚɑ̃n] without a prothetic [ɛ].) The innervation of [spread] fneuron in event e (in conjunction with the correct state of volitional control circuits) will cause a signal to be sent to the motor control system that will ultimately innervate the descending laryngeal nerve to innervate the posterior cricoarytenoid muscle (and reciprocally de-innervate the lateral cricoarytenoid muscle). On the perception side, we assume (facts not in evidence because we’re too lazy to look through all of the STRFs in Mesgarani et al 2008) that there are auditory neurons whose STRFs calculate the intensity difference between bark bands 1 and 2 as versus bark bands 3 and 4 (probably modulated by the overall spectral tilt in bark bands 5 to 10). The greater this intensity difference the more likely a [spread] fneuron is to be innervated (activated past threshold). We doubt that there’s much effect of volitional control on the perceptual side, as auditory MMNs can be observed in comatose patients, or at least in those that eventually recover, 30/33 patients in Fischer, Morlet & Giard 2000. To Charles's point last week about phonological delusions, it's well known that large positive values of voice onset time (VOT) can signal [spread] also, without the inclusion of voice quality differences in the first few pitch periods of the vowel. So the working hypothesis is that the neurons for [spread] are connected to auditory neurons with at least two kinds of STRFs, the bark-based one mentioned above, and a neuron yielding a double-on response, see various publications by Steinschneider.

As many people are aware, graphs (and multigraphs) are usually defined over sets (or bags or multisets) of vertices and edges. We haven’t included the set stuff here. Why not? The idea, for the moment at least, is that we’re calculating in a workspace, and there isn’t significant substructure in the workspace in terms of individuated phonological forms. So the workspace universe provides the set structures, such as they are, the events, the properties of the events and the relations between events. This could well be a big mistake, as it seems to preclude asking (or answering) questions like “do these two words rhyme?” as this would involve comparing sub-structures of two different phonological representations. That is, in order to evaluate rhyme (or alliteration, or …) we would have to evaluate/find a matching relation between two sub-graphs, so we would need to be able to represent two separate graphs in the workspace and know which one was which. To do this we could add labels to keep track of multiple representations, or add the extra set structure. There are (different) mathematical consequences for either move, and it isn’t at all clear which would be preferable. So we won’t do anything for now. That is, we’re wimping out on this question.

Finally, we will say once more that there are some strong similarities between this approach and Carson-Berndsen’s work. But in Time-Map Phonology time is represented using intervals on a continuous linear timeline whereas here we have discretized time instead and we allow precedence to be non-linear.

Next time: It’s Musky